A team of 24,576 experts
The model is split into small specialists. Each word only needs 10 of them, so almost all of the model rests at any moment.
Built on the open-source Strata engine
Strata runs Qwen3.8-Flash-Next on one 12 GB graphics card and ordinary RAM. Private, free and fast.
The model is split into small specialists. Each word only needs 10 of them, so almost all of the model rests at any moment.
Strata learns which experts get used most and keeps them in VRAM. On a 12 GB card that is about 4,300 of them.
Every expert sits in ordinary RAM. When a word needs one that is not on the card, your processor computes it at the same time.
A small helper guesses the next few words and the big model checks them in one pass. Same answer, 1.6 to 1.8 times sooner.
Strata is the engine. This site helps you decide, see and compare before you download 70 GB.
Real answers recorded on an RTX 5070, replayed at their true speed with the hardware beside them.
Open the replays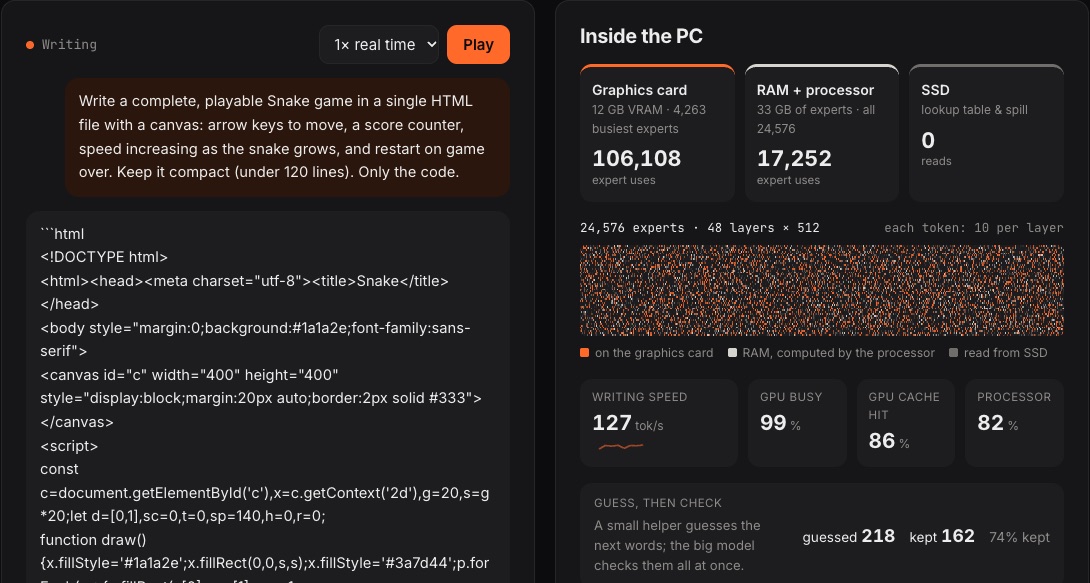
Enter your graphics card and RAM. Get the model size that fits and the speed people measured on it.
Check yours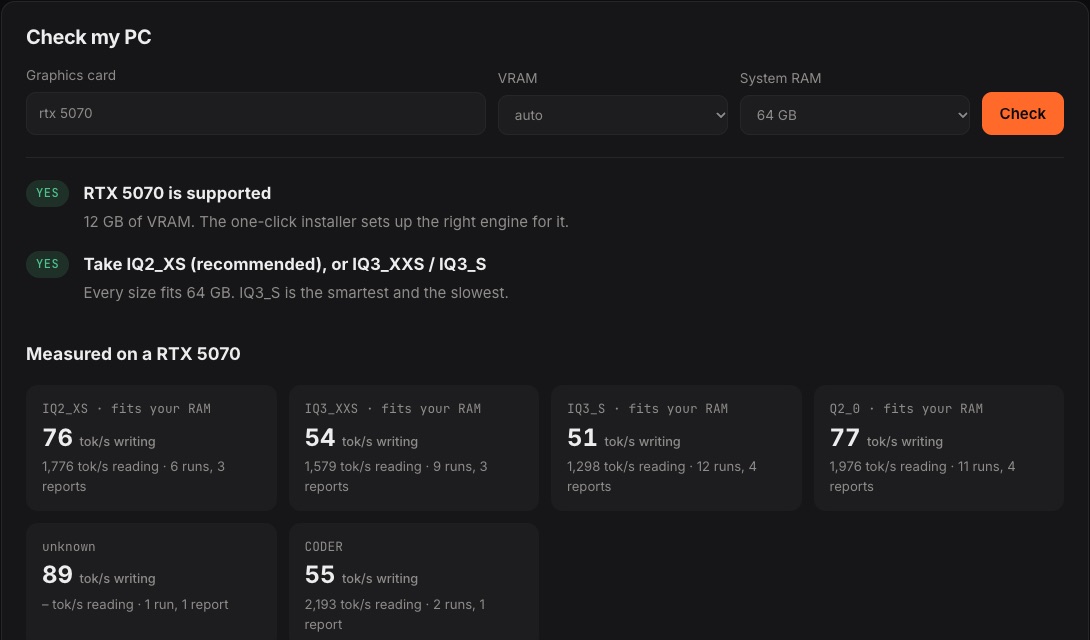
Each hour we read new reports from the Strata repo and turn them into one table you can search.
# Download the zip, unzip it, then double-click:
START-HERE.bat
# Press Enter for the recommended answers.
# It downloads the model (about 70 GB) and opens the app.
git clone https://github.com/Niko1221/Strata.git
cd Strata
./setup.sh# Apple Silicon, macOS 15 or newer (experimental)
xcode-select --install
git clone https://github.com/Niko1221/Strata.git
cd Strata
./setup.sh
# builds the Metal engine, about 7 minutes# After setup, Strata serves its app here:
http://127.0.0.1:8080
# Chat, a live Monitor of GPU, CPU and RAM, and About.
# Next time, run START-HERE.bat or ./setup.sh again.from openai import OpenAI
client = OpenAI(base_url="http://127.0.0.1:8080/v1", api_key="local")
reply = client.chat.completions.create(
model="strata",
messages=[{"role": "user", "content": "Explain VRAM in one line"}],
)
print(reply.choices[0].message.content)# Point Claude Code at your own PC
ANTHROPIC_BASE_URL=http://127.0.0.1:8080 claude
# Codex CLI and other Responses API apps use /v1/responsescurl http://127.0.0.1:8080/v1/chat/completions \
-H "Content-Type: application/json" \
-d '{"model": "strata",
"messages": [{"role": "user", "content": "Hi!"}]}'Your code, documents and chats stay on your own disk. No account, no logs on someone else's server.
No subscription and no bill per token. Strata is MIT licensed.
Once the model is downloaded, it needs no internet.
About 80 tokens a second on a 12 GB card, faster than you read.
125 billion parameters. The kind of model that usually needs a server, now reading pictures, writing code and working with agents.
Claude Code, Codex, Cursor and your scripts connect through the same API.
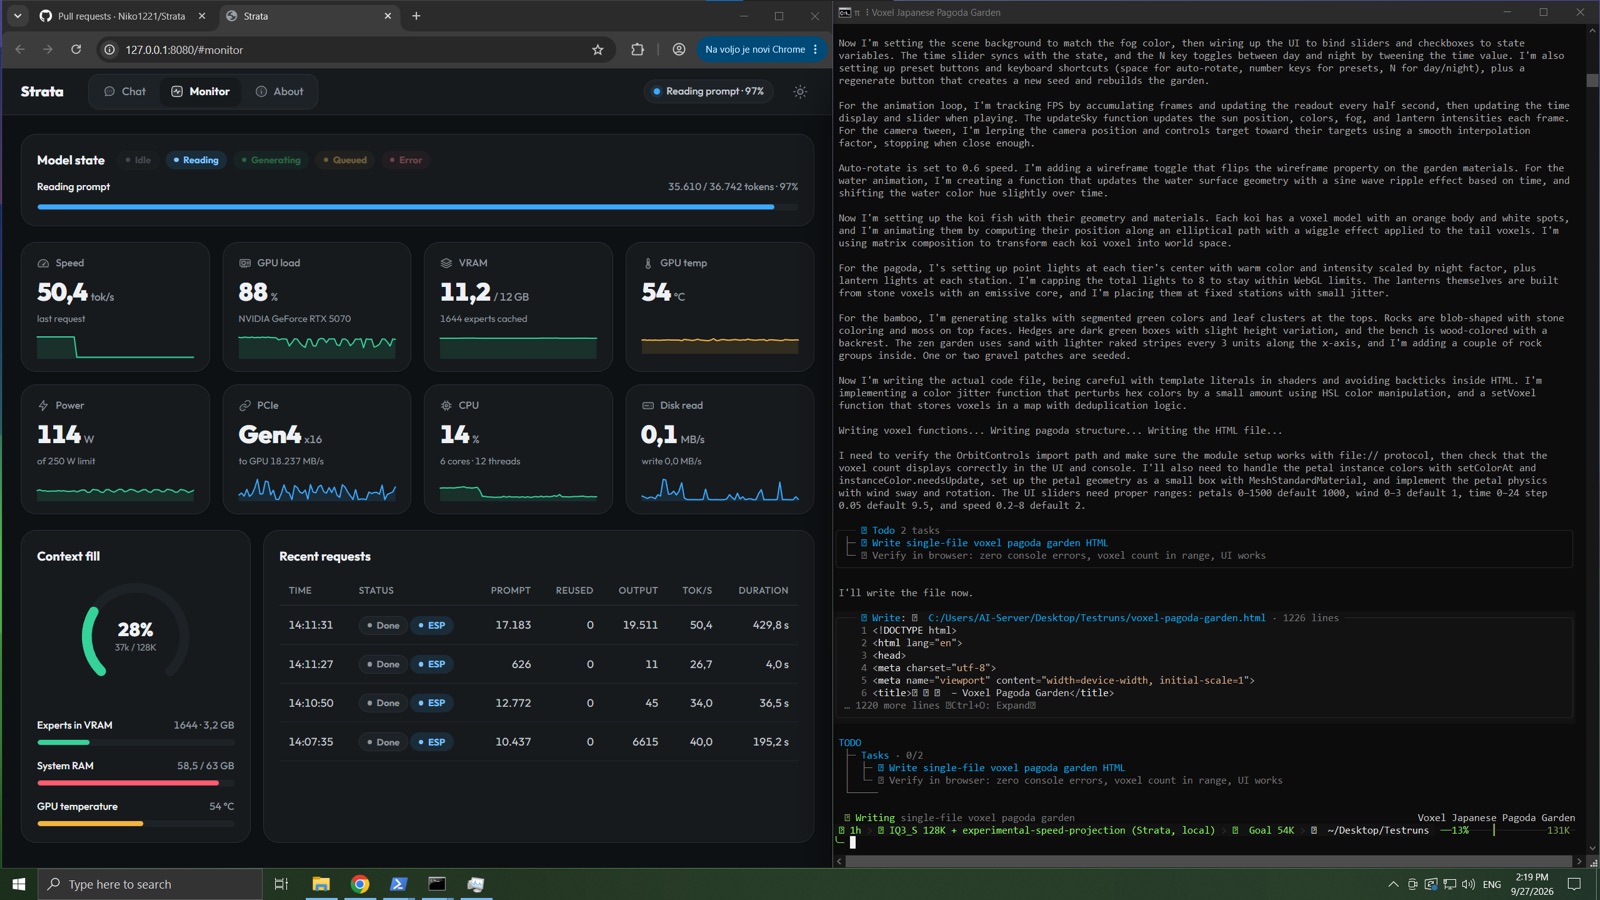
Strata is the open-source engine that makes all of this possible. It runs the Qwen team's model, compressed by ISTA-DASLab, Unsloth and others, and builds on llama.cpp. We are a community site, not part of the project.